RedactionBench
- A10 Networks, Inc.
* Corresponding author: sbrynjolfson@a10networks.com
Abstract
As we integrate intelligent systems beside sensitive and private data, we need the ability to redact information to balance utility and safety. In RedactionBench, we pose redaction as a property detection task, thereby transcending any particular taxonomy to discuss frameworks of machine privacy directly. We introduce RedactionBench, a challenging set of 200 diverse documents which have been exhaustively manually annotated for sensitive content, and the R-Score, our metric designed to nullify shallow formatting decisions. In our user study, we demonstrate users have differing privacy expectations and that these differences are concentrated in our contextual units: mean pairwise agreement of mandatory (81.7%), benign (84.1%), and background units (88.7%), are significantly higher than our contextual units (63.8%). We provide comprehensive evaluations of 44 models across a wide range of architectures. While Claude Opus 5.5 scores the highest at 0.832, we demonstrate that a simple base Qwen3.8-27B in the mini-swe-agent harness achieves 0.740, outperforming the strongest PII-specific model, PII-Tracer, by +13.83%.
Interactive R-Score
Select text to redact it; click a redaction to remove it. On mobile, use Randomize redactions to explore different combinations.
Evaluations
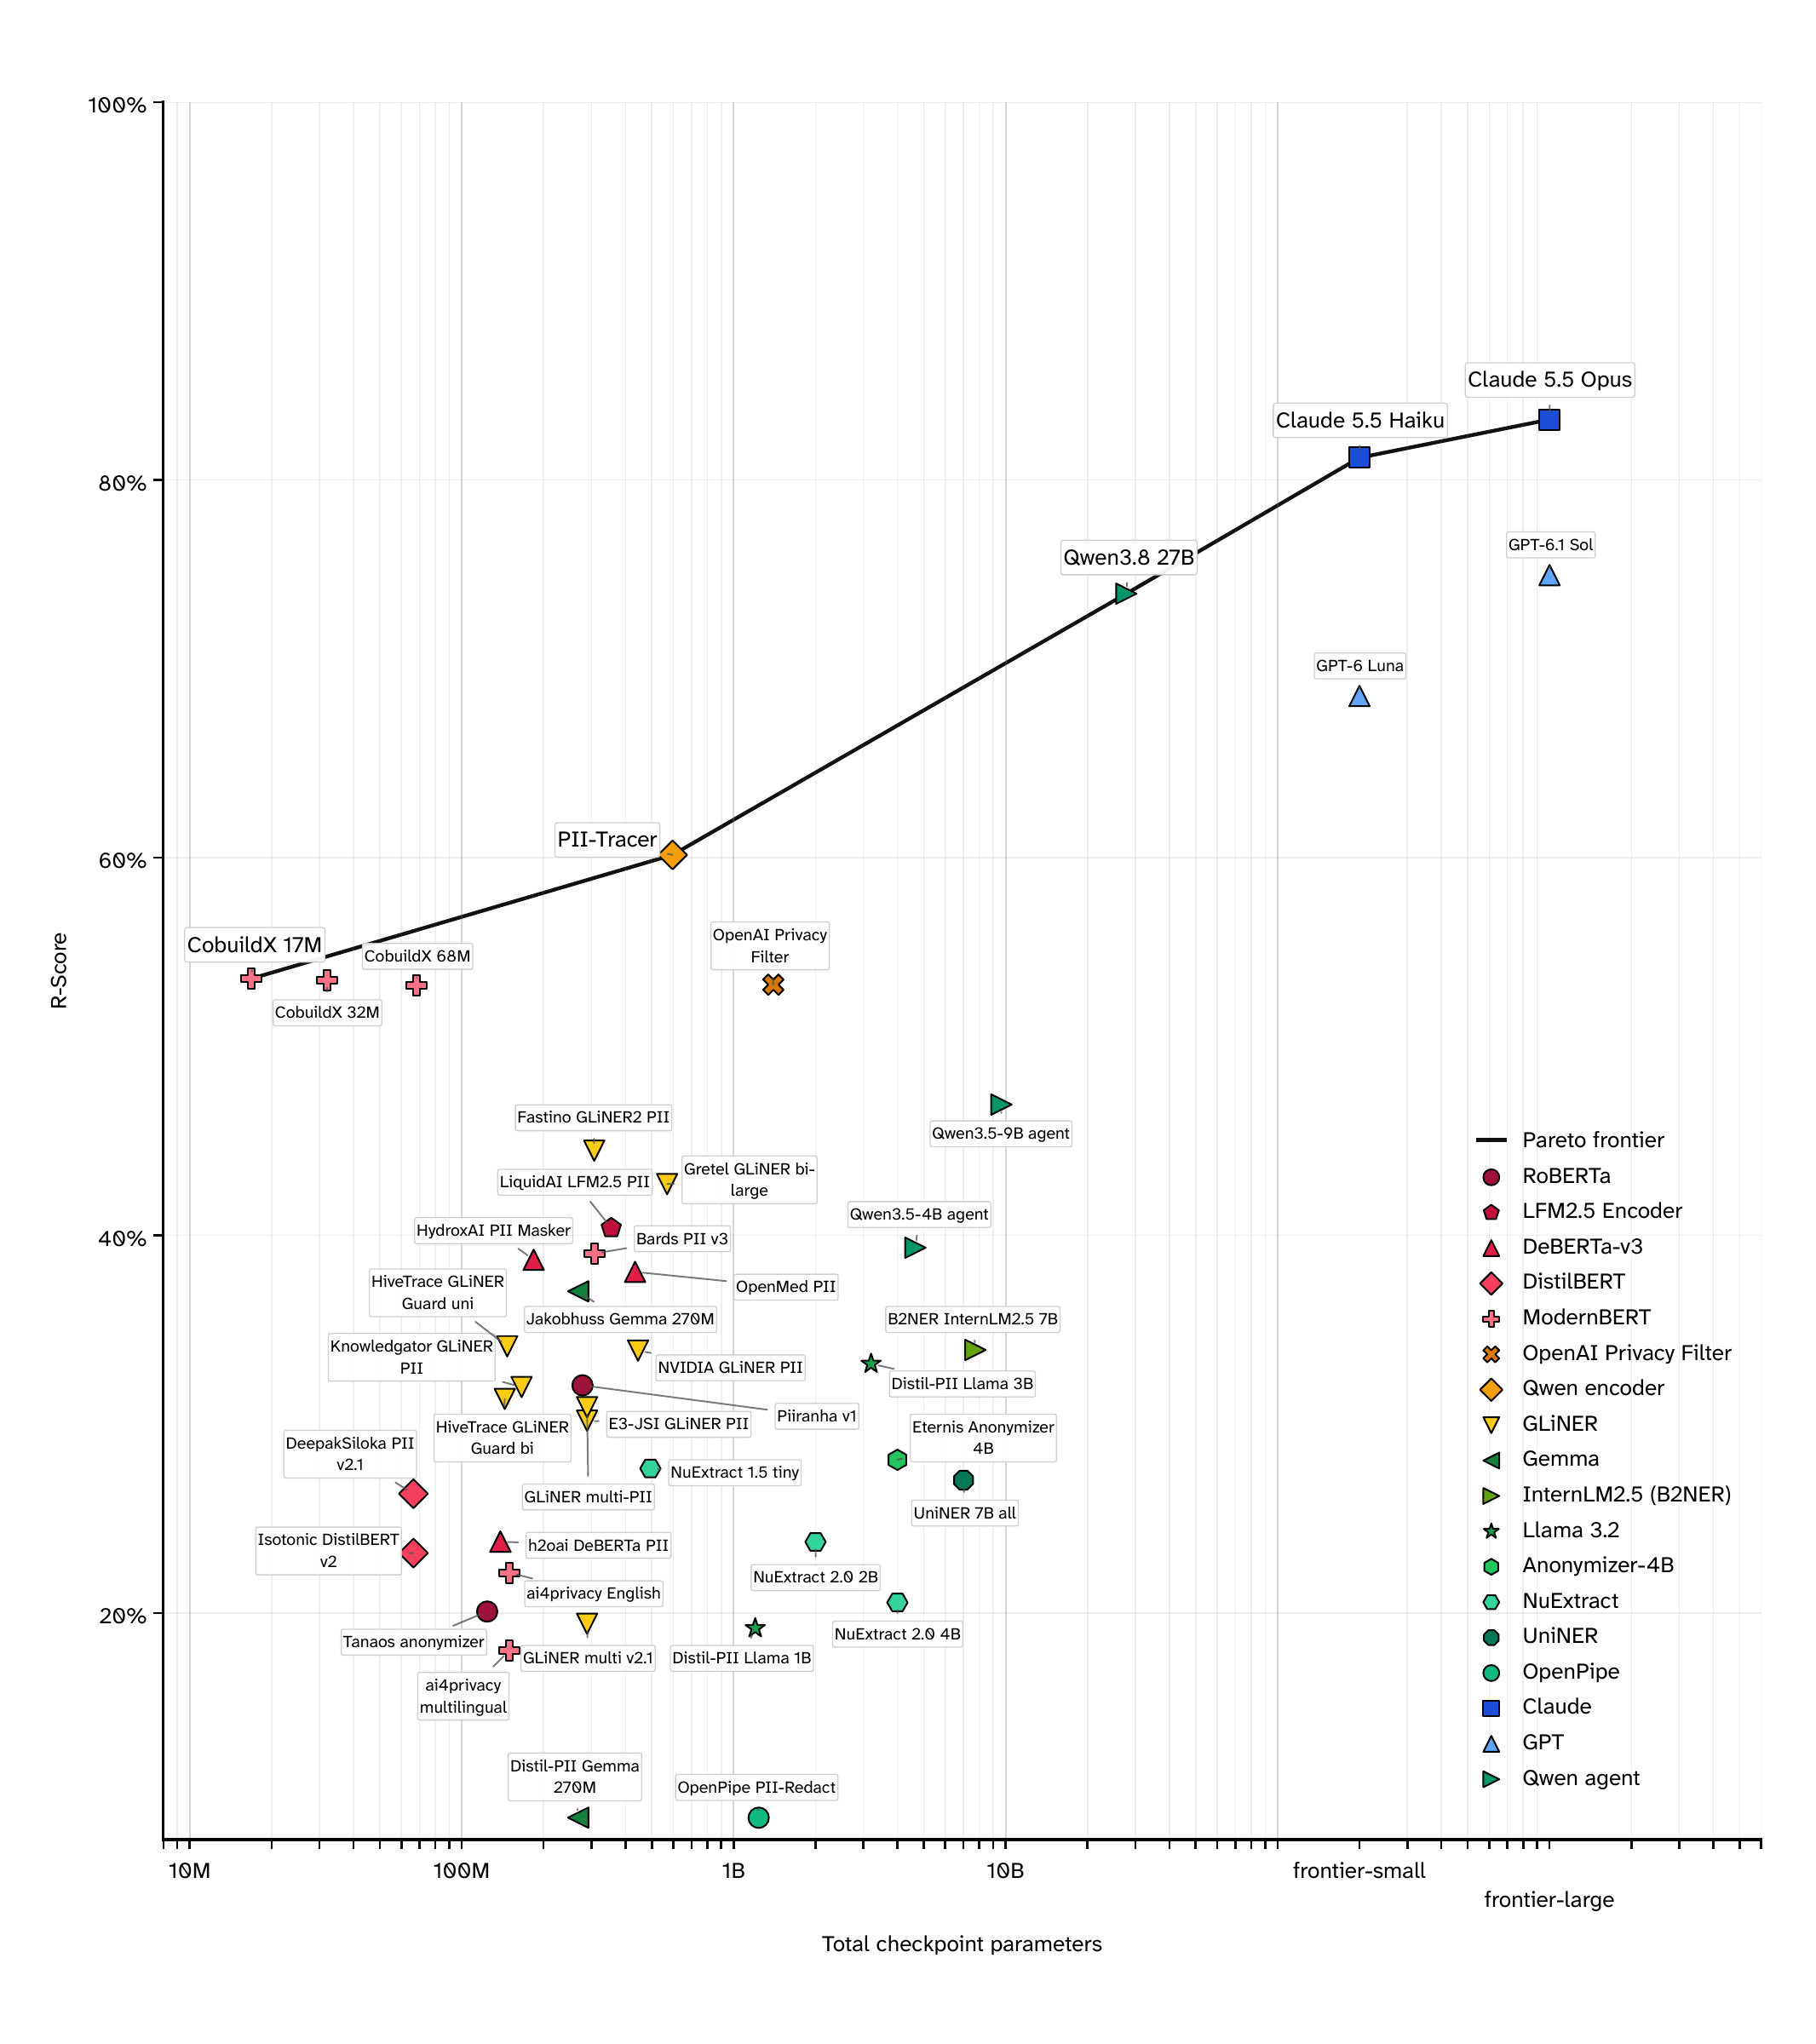
Overall Model Leaderboard
† h2oai/deberta_finetuned_pii and lakshyakh93/deberta_finetuned_pii are mirrored uploads of the same checkpoint and produce identical scores.
Data Samples
Citation
@misc{brynjolfsson2026redactionbench,
  title         = {RedactionBench},
  author        = {Brynjólfsson, Sean and Jayakrishnan, Shashvat and Sali, Esha and Purwar, Diptanshu and Aggarwal, Madhav},
  year          = {2026},
  eprint        = {2606.18782},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CL},
  doi           = {10.48550/arXiv.2606.18782},
  url           = {https://arxiv.org/abs/2606.18782}
}